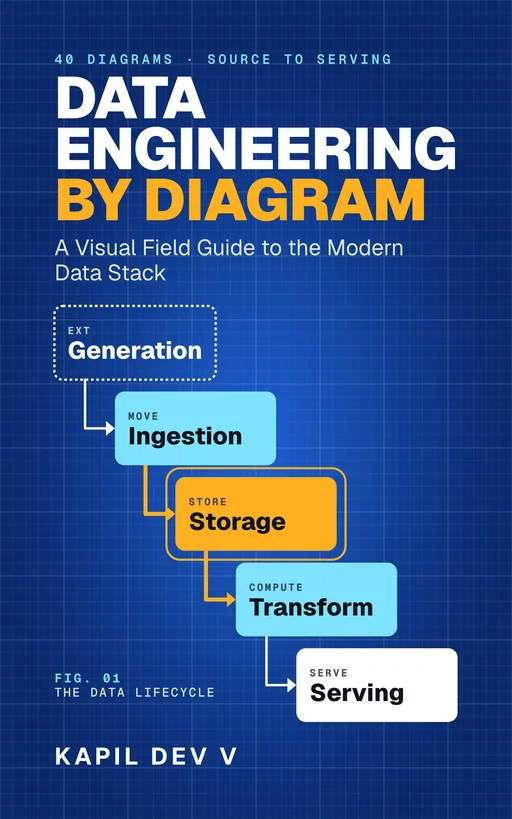
Data Engineering by Diagram
A Visual Field Guide to the Modern Data Stack
by Kapil Dev V
A visual field guide to the modern data stack. Forty diagrams carry the explanation, and the prose walks you through each one, in twenty-two short chapters from the source system to the dashboard. It is vendor-neutral: the shapes hold whether your stack runs on Databricks, Snowflake, Fabric or a laptop.
The Kindle eBook. Amazon.in in India, Amazon.com outside India.
Inside the book
- Batch, micro-batch and streaming, full loads, incremental loads and CDC
- Warehouse, lake, lakehouse and lakebase, and what each one solved
- Columnar file formats, partitioning and open table formats
- ETL and ELT, and why the order matters more than the letters
- Distributed computing from HDFS and MapReduce to Spark's driver and executors
- Idempotency, watermarks, upserts, backfill, late data and exactly-once delivery
- Star and snowflake schemas, Inmon, Kimball and data vault, slowly changing dimensions
- Medallion architecture
- Orchestration and the DAG
- Lambda and Kappa architectures, stream windows and state
- Data mesh, data fabric and who owns what
Written for the analyst moving into engineering, the software engineer inheriting a pipeline, and the engineer who can build the thing but wants the whole map in an afternoon.